The team behind Molecular Assets
Founder · Molecular Assets
Stephen K. Boyer, Ph.D.
Medicinal chemistry · Scientific informatics · Patent intelligence
Stephen Boyer works at the intersection of medicinal chemistry and computer science. His career includes more than a decade in the pharmaceutical industry at Novartis, over 25 years at IBM Research, and five years as a scientific advisor to Google.
He helped pioneer computer-assisted curation of patents and scientific literature and was instrumental in launching the IBM Patent Server, one of the earliest publicly accessible patent-search services. His contributions to intellectual property information were recognized with the 2014 Intellectual Property Information (IPI) Award.
His work spans scientific-data infrastructure, text and image analytics, and applications of machine learning to molecular information. He has collaborated across industry, academia, and government to improve access to scientific knowledge.
Dr. Boyer holds a B.A. from Temple University and a Ph.D. in synthetic organic chemistry from Tufts University. He has authored numerous publications and patents covering drug synthesis, information analytics, and data infrastructure.
Professional biography adapted from the founder's supplied biography.
Co-founder · Molecular Assets
Mike Moser, Ph.D.
Computer science · Data storage technologies · Scientific software
Mike Moser is a computer scientist with extensive experience in computer systems and data storage technologies. He completed his undergraduate degree at Brown University and earned his Ph.D. from the California Institute of Technology (Caltech).
Before Molecular Assets, Dr. Moser worked for several years in computer storage technologies at IBM Research and at storage companies including SanDisk and Western Digital.
At Molecular Assets, he contributes his computer science expertise to the company's scientific information and AI-enabled technology platform.
Four decades of curated scientific information.
After 10 years at Ciba-Geigy (now Novartis), Steve joins IBM Research and develops the IBM Patent Server, the first open-access patent server. He later founds Collabra, Inc. and continues to work for IBM Research, contracted to the Watson project, an early healthcare AI.
Collabra is contracted by Google to curate scientific information. Billions of open-source molecular, biological, and medicinal entities are made publicly available for the good of the scientific community.
Collabra launches Molecular Assets together with Mike to continue the availability of curated scientific data and relationships in the scientific community.
Molecular Assets enhances data curation, aggregation, and integration into relevant information retrieval systems.
Scaling up the curation process
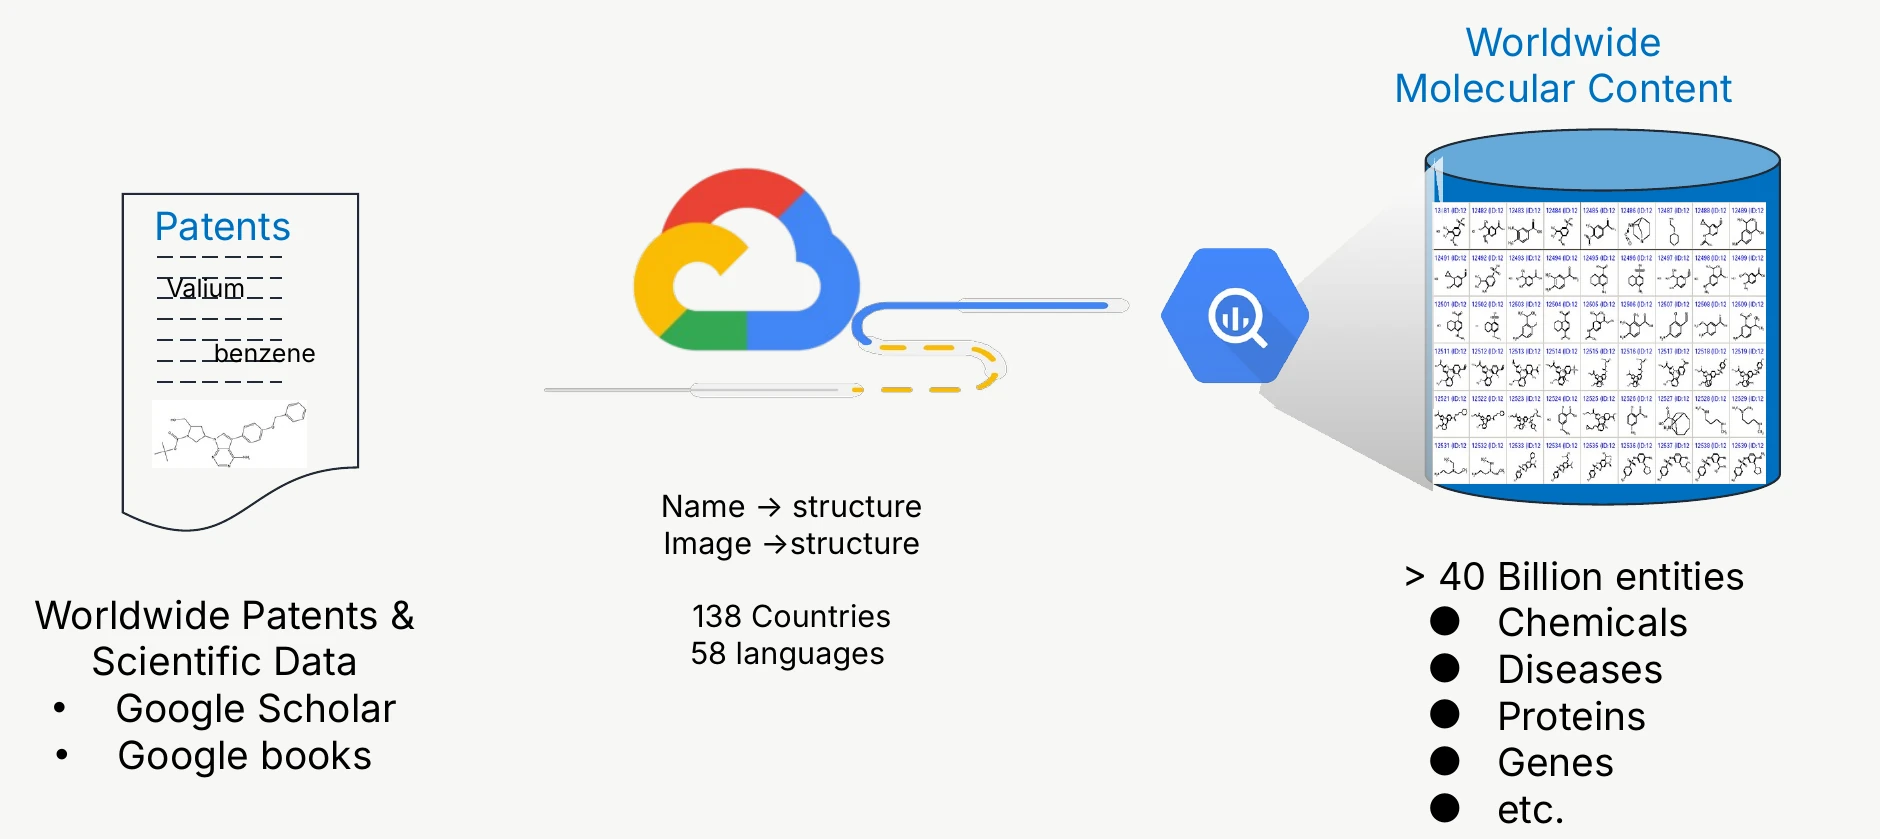
Worldwide patents and scientific data from Google Scholar and Google Books were processed with name-to-structure and image-to-structure conversion across 138 countries and 58 languages, producing more than 40 billion entities: chemicals, diseases, proteins, genes, and more.